
LLM Hosting in 2026: Local, Self-Hosted and Cloud Infrastructure Compared
Strategic guide to hosting large language models locally with Ollama, llama.cpp, vLLM, or in the cloud. Compare tools, performance trade-offs, and cost considerations.
Control data and models with self-hosted LLMs
Self-hosting LLMs keeps data, models, and inference under your control-a practical path to AI sovereignty for teams, enterprises, nations.
LLM speed test on RTX 4080 with 16GB VRAM
Running large language models locally gives you privacy, offline capability, and zero API costs. This benchmark reveals exactly what one can expect from 14 popular LLMs on Ollama on an RTX 4080.
January 2026 trending Go repos
The Go ecosystem continues to thrive with innovative projects spanning AI tooling, self-hosted applications, and developer infrastructure. This overview analyzes the top trending Go repositories on GitHub this month.
Self-hosted ChatGPT alternative for local LLMs
Open WebUI is a powerful, extensible, and feature-rich self-hosted web interface for interacting with large language models.
Real AUD pricing from Aussie retailers now
The NVIDIA DGX Spark (GB10 Grace Blackwell) is now available in Australia at major PC retailers with local stock. If you’ve been following the global DGX Spark pricing and availability, you’ll be interested to know that Australian pricing ranges from $6,249 to $7,999 AUD depending on storage configuration and retailer.
Testing Cognee with local LLMs - real results
Cognee is a Python framework for building knowledge graphs from documents using LLMs. But does it work with self-hosted models?
Related guides for persistent knowledge layers — agent memory plugins, graph tooling, and stack context — live under the AI Systems Memory hub.
Type-safe LLM outputs with BAML and Instructor
When working with Large Language Models in production, getting structured, type-safe outputs is critical. Two popular frameworks - BAML and Instructor - take different approaches to solving this problem.
Thoughts on LLMs for self-hosted Cognee
Choosing the Best LLM for Cognee demands balancing graph-building quality, hallucination rates, and hardware constraints. Cognee excels with larger, low-hallucination models (32B+) via Ollama but mid-size options work for lighter setups.

Build AI search agents with Python and Ollama
Ollama’s Python library now includes native OLlama web search capabilities. With just a few lines of code, you can augment your local LLMs with real-time information from the web, reducing hallucinations and improving accuracy.
Build AI search agents with Go and Ollama
Ollama’s Web Search API lets you augment local LLMs with real-time web information. This guide shows you how to implement web search capabilities in Go, from simple API calls to full-featured search agents.
Compare the best local LLM hosting tools in 2026. API maturity, hardware support, tool calling, and real-world use cases.
Running LLMs locally is now practical for developers, startups, and even enterprise teams.
But choosing the right tool — Ollama, vLLM, LM Studio, LocalAI or others — depends on your goals:
Deploy enterprise AI on budget hardware with open models
The democratization of AI is here. With open-source LLMs like Llama, Mistral, and Qwen now rivaling proprietary models, teams can build powerful AI infrastructure using consumer hardware - slashing costs while maintaining complete control over data privacy and deployment.
GPT-OSS 120b benchmarks on three AI platforms
I dug up some interesting performance tests of GPT-OSS 120b running on Ollama across three different platforms: NVIDIA DGX Spark, Mac Studio, and RTX 4080. The GPT-OSS 120b model from the Ollama library weighs in at 65GB, which means it doesn’t fit into the 16GB VRAM of an RTX 4080 (or the newer RTX 5080).
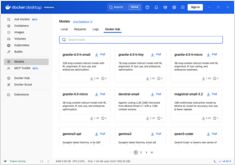
Compare Docker Model Runner and Ollama for local LLM
Running large language models (LLMs) locally has become increasingly popular for privacy, cost control, and offline capabilities. The landscape shifted significantly in April 2025 when Docker introduced Docker Model Runner (DMR), its official solution for AI model deployment.