
Tiered Context: A Knowledge Hierarchy for AI Agents
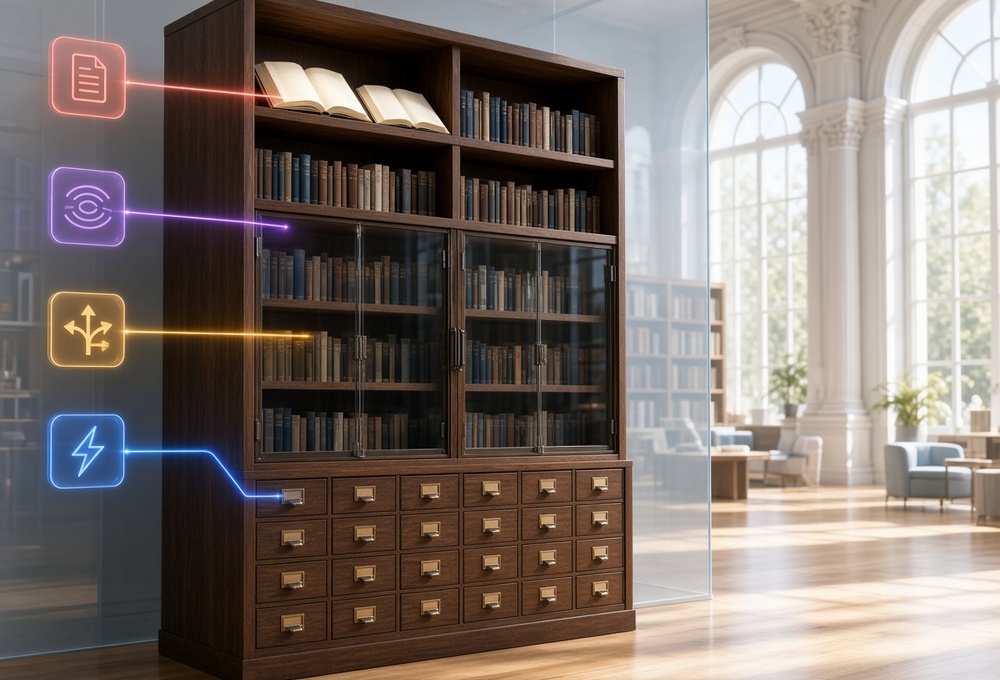
Five-layer knowledge hierarchy for agent memory.
An agent with one flat memory file does not forget things; it cannot stop remembering things it was not asked about. The fix is a tiered context where each knowledge layer enters through a different trigger.
The failure mode is not forgetting, it is the opposite. In one flat store every fact lives in the same place, enters context the same way, and is therefore available the same way — always. Ask the agent about a client email and it narrates the router configuration while drafting the reply; ask it to troubleshoot a service and it mentions the sponsorship rate quoted last month. The memory pile is a monolith: any change to one concern touches every other concern, and the blast radius of every query is the entire corpus.
The standard advice is behavioral: teach the agent what is relevant to the current topic. That is the software equivalent of writing “please be careful” on a load-bearing wall — the agent can be instructed, and it will mostly comply, until the day it does not. The structural alternative is knowledge that cannot enter a conversation unless the activity that needs it is already happening. This article defines that structure as a five-layer knowledge hierarchy — what each layer is, what triggers its injection, what belongs in it, and where it fails — and applies it to a concrete multi-domain setup: one general profile, one for a homelab, one for personal matters, one for work, one for education.
Naming the hierarchy
There is no single industry-standard term, so the definition here is explicit. A knowledge hierarchy is a stratified arrangement of what the agent knows, where each stratum differs in three properties: how it enters the model’s context, how large it is allowed to be, and how long it is expected to stay correct. At the knowledge-architecture level, the neighboring paradigms — PKM, RAG, wikis, and memory systems — are compared in PKM vs RAG vs Wiki vs Memory Systems, and the runtime contracts assistants actually implement are mapped in Memory Systems in AI Assistants. Both sit inside the Knowledge Management cluster, which covers the foundations, methods, and tools of human knowledge systems. This article adds the trigger-based classification and the profile boundary that make placement enforceable.
Two lineages explain the shape of the hierarchy.
The first is the CPU memory hierarchy. A processor does not store every byte it might ever need in the same register. It has L1 cache — small, always resident, accessed with zero decision-making — L2, main memory, and disk, each layer larger, slower to reach, and accessed only when the upper layers do not have the answer. The design rule is not “keep everything fast.” It is most data rarely matters; pay access cost only when it does. An agent with one flat memory file is a CPU with everything crammed into L1: the register file is huge, so everything is visible, including the bytes the current instruction did not ask for. MemGPT made the same move for agents, modelling memory as tiers with explicit movement between fast and slow stores.
The second is the cognitive memory taxonomy, which divides knowledge into procedural memory (how to do things), semantic memory (facts about the world), and episodic memory (what happened, when, to whom). The taxonomy matters because the failure modes differ by type: procedural knowledge that goes stale is a bug in your workflow, semantic knowledge that goes stale is a wrong fact, and episodic knowledge that leaks is a privacy incident. A hierarchy organized by content type, not by location, tells you which failures are dangerous.
The organizing axis for this article is neither of the above. Classify knowledge by what causes it to enter context. The injection trigger is the mechanism, and the mechanism is what you can actually enforce. An agent system offers exactly four triggers:
- Always. Injected into every turn, unconditionally.
- Task trigger. Loaded when the current activity matches a declared condition.
- Semantic recall. Surfaced when the current message is similar to something stored.
- Explicit reference. Fetched because a task names the file or the query.
Every layer of the hierarchy is defined by which trigger feeds it. That is the whole design, and the rest of this article is an elaboration of one table.
The five layers
| Layer | What it is | Injection trigger | Typical carrier | Size discipline | Fails as |
|---|---|---|---|---|---|
| 0 — Identity | Who the agent is, how it talks, what it will not do | Always | SOUL.md or equivalent | Small; changes rarely | Bloat — identity becomes a fact store |
| 1 — Resident memory | Durable facts that apply to every session | Always | MEMORY.md / USER.md or equivalents | Budgeted in characters; pointer-dense | Monolith — domain facts migrate in |
| 2 — Procedural | How to do recurring tasks, plus where their data lives | Task trigger | Skills | Bounded per skill; procedures, not data | Data creep — skills become databases |
| 3 — Reference | The system of record: tables, configs, contracts, runbooks | Explicit reference | Files, wiki | Unbounded; greppable, versioned | Staleness — nobody updates the record |
| 4 — Retrieved memory | Episodic and relational facts: decisions, exchanges, state changes | Semantic recall | A memory backend with retrieval (e.g. a vector/graph store) | Budgeted per recall; tag-scorable | Bleed — recall surfaces the wrong domain |
Read the table down the trigger column, not across. Layer 0 and Layer 1 are the L1 cache: they pay for their always-resident privilege by being tiny. Layer 2 is instruction cache: pulled on a branch condition, the task matching the skill’s trigger. Layer 3 is disk: it can be enormous because nothing enters context until a step of a task explicitly reads a named file. Layer 4 is the awkward one — it is main memory, accessed by similarity, which is the only trigger in the list that does not involve a decision made by you or by the task. Similarity is a probabilistic gate, and that is why it needs the strictest external controls, which the profile section provides. The cabinet image at the top of this article encodes the same idea: the higher a tier sits, the more freely its contents enter a conversation, and the glass partition marks where one domain’s shelf ends.
Layer 0: identity
SOUL.md, or whatever your agent calls its system prompt. Its job is to define who, not what: tone, values, refusal boundaries, and memory policy. The memory policy belongs here because it is the only instruction that must be in force before any memory is consulted. An identity file that starts listing server names, client names, or rates has already failed — it has become Layer 1 content wearing Layer 0’s badge, and it now rides into every conversation, including ones where it must not appear.
Layer 1: resident memory
The persistent memory files: general notes and the user profile. Two rules govern this layer, and they are the rules that separate a working hierarchy from a pile.
First, pointers, not facts. If a fact serves only one domain, it does not belong here. The correct entry is not the fact itself but a signpost:
Infra facts: wiki/infra/ + memory bank 'homelab'.
Clients and contracts: wiki/business/clients/ + bank 'business'.
The signpost is domain-neutral, so it is safe to carry everywhere. The fact it points at is loaded only by the activity that named the destination.
Second, a hard budget, enforced. If the store has no character limit, it fills, and the filling is always with the most recently discussed topic — so an infra week quietly evicts or surrounds the general context with infra. A budget that is nearly full forces triage, and triage is the only mechanism that keeps this layer honest. The Hermes implementation is a working example: MEMORY.md capped at 2,200 characters and USER.md at 1,375, injected as a frozen block at session start, is documented in Hermes Agent Memory System.
Layer 2: procedural knowledge
Skills are how the agent encodes how: the procedure, the pitfalls, and — critically for this article — the pointers into the deeper layers. A skill for homelab administration names which wiki directory holds the inventory and which memory bank to recall. A skill for client work names the contract store and the business bank. The skill’s description is its trigger: it is the branch condition that decides whether the procedure, and therefore its pointers, enter context at all.
This is the layer that makes the hierarchy work operationally, because it is the seam between “what activity is happening” and “what data that activity may see.” A task about a client email loads the client skill; the client skill names the business bank and the contracts directory; the homelab bank and the infra directory are simply never referenced from a path the task walked.
The failure mode is data creep: pasting the actual client list or the actual IP table into the skill body. Then the data is always loaded whenever the procedure is, and the procedure’s trigger has become the data’s exposure boundary. Skills carry the path to the data, and nothing else that is sensitive.
Layer 3: reference data
The wiki, the notes tree, the system of record. This is the layer with the fewest constraints and the fewest surprises, because it is the only layer with a deterministic access path: something enters context only because a step of a task explicitly read that file. Tables, inventories, contracts, runbooks, statistics — the stuff you would keep in a database or a configuration management system. When the corpus is LLM-maintained, the LLM Wiki pattern applies: synthesis happens at ingest time, and the result is stored as structured, linked pages.
The reason reference data belongs here and not in Layer 4 is that retrieval quality is the wrong tool for tables. Semantic recall is excellent for “what did client X confirm about the deadline” and terrible for “what is the port of the service on host Y” — the latter has exactly one correct row, and a reranker returning the three nearest paragraphs is a liability. Deterministic lookup wins for reference data; similarity wins for episodes. Keep them apart, and each layer’s access pattern matches its content shape.
The failure mode is staleness, which is a maintenance problem, not an architecture problem: the record drifts from reality and the agent, doing everything right, works from a wrong table. The mitigation is the same one any system of record needs — one writer per file, change logs, and an audit cadence — plus the drift-detection and contradiction-check practices covered in LLM Wiki Maintenance: Drift, Contradictions and Review.
Layer 4: retrieved memory
A memory backend with per-turn automatic recall: the agent’s episodic and relational memory. Decisions and their dates, “client X confirmed Y,” “we tried Z and it did not work.” This is where the dynamic, self-organizing part of the system lives — and where the security story gets interesting, because semantic recall is a probabilistic gate and probabilistic gates bleed.
“Billing question for client X” and “which host runs the billing server” are close in embedding space. Any single bank that holds both the client records and the infrastructure inventory will, with non-trivial probability, surface the latter in the former. You can narrow this with tags and recall restrictions, and you should — but a tag filter on a mixed corpus is a discipline, not a structure. The structural answer is to stop mixing: one bank per domain, so that the bleed radius of a recall is, by construction, one domain. Choosing the backend itself — capture policy, dependencies, self-hosting constraints — is a separate comparison, covered in Agent Memory Providers Compared.
Two mechanical details matter when you wire this layer. Write paths and read paths are separate controls: a bank can be included in recall while being excluded from retention, which is how you build a profile that reads everything and writes to nothing. And every bank should carry its own retention mission — a short statement of what that bank exists to hold. A business bank with the mission “client correspondence, contract terms, negotiation state; never infrastructure details” will extract accordingly, because extraction is an LLM call that reads the mission. OpenAI’s personalization cookbook treats consolidation as the most sensitive and error-prone stage of a memory lifecycle — the retention mission is the contract that keeps that stage honest.
Profiles: the boundary that makes separation structural
Up to here, the hierarchy separates knowledge by layer — necessary but not sufficient. The five layers above are one agent’s anatomy. The question this article started with is about domains: homelab, personal, work, education, and the general context that spans them.
The mechanism for domain separation is the profile — a full, independent instance of the agent: its own identity file, its own resident memory, its own skills directory, its own scheduled jobs, and, decisively, its own memory-bank wiring. A profile is not a tag on a conversation; it is a separate system that happens to share a machine. When you run agent -p homelab, you get a process whose entire Layer 0 through Layer 4 is scoped to the homelab domain, and whose recall pool cannot contain the business bank because the business bank is not in its configuration at all.
This is the difference between the two answers to the leak problem. “Do not disclose infrastructure in business conversations” is a prompt instruction — a probability. “The business profile’s recall pool does not include the infrastructure bank” is a configuration — a guarantee. The hierarchy tells you what goes where; the profile boundary is what makes the placement un-bypassable from inside the conversation.
The worked example, five domains:
| common (default) | homelab | personal | work | education | |
|---|---|---|---|---|---|
| Identity (L0) | Shared base + memory policy | Base + “infra operator” frame | Base + “private, no business tone” | Base + “professional, client-facing” | Base + “teacher, assume no prior knowledge” |
| Resident memory (L1) | Pointers only — to the four domain homes | Homelab pointers, machine facts | Personal pointers | Work pointers | Course pointers |
| Skills (L2) | General workflow skills | Infra skills, runbook skill, monitor skill | — | Client-operations skill, outreach skill | Lesson-planning skill |
| Reference (L3) | Shared index of the wiki | wiki/infra/ | wiki/personal/ | wiki/business/clients/ | wiki/education/ |
| Retained bank (L4) | None (read-only) | bank: homelab | bank: personal | bank: business | bank: education |
| Recall-only banks (L4) | homelab, personal, business, education | — | — | — | — |
Two cells in that table do the heavy lifting.
The common profile’s bank row is “none, read-only”. The general conversation is where you ask cross-cutting questions, so it should be able to see every domain’s recalled facts — but it must not write to any of them. Chatter in a general session is exactly the material you do not want extracted into a domain’s durable memory, and the read-only wiring removes the choice from the model entirely. If the backend’s wiring supports recall-only bank lists (separate from write banks), this is one configuration line per domain bank; if it does not, the common profile recalls from a dedicated general bank and you accept a weaker cross-domain view.
The domain profiles’ recall rows are empty. Each domain profile sees exactly one bank. The homelab profile will never recall a client’s contract term, not because it was told not to, but because the term is not in the pool it queries. This is the bidirectional separation the whole exercise is for: it works symmetrically by construction, with no instruction involved in either direction.
Three operational consequences follow, and they are why the profile approach costs more than the single-agent approach but is worth it for anyone whose domains are genuinely disjoint.
- The trigger becomes the surface. If the homelab work happens in a terminal you launch with
-p homelab, and client work happens on a messaging account routed to the work profile, then which hat you are wearing is a property of how you invoked the agent, not a flag you remember to state. Misdirection — accidentally running client tasks in the homelab context — becomes as visible as running the wrong shell. - Scheduled work inherits the boundary. Cron jobs and delegated sub-tasks run inside whichever profile owns them. A nightly infra check scheduled in the homelab profile cannot drift business content into the homelab bank, because it never has it.
- The filesystem is shared, and that is the honest limit. Profiles separate context, not access. Every profile’s terminal can read every profile’s files; the boundary protects conversations, not disks. So the layers that hold genuinely sensitive material need their own discipline: credentials in an environment file or a secret store rather than in wiki plaintext, the wiki outside any public repository, and per-directory permissions where the OS helps. Treat the profile boundary as a firewall for context — excellent at its job — and do not let it be mistaken for one for data.
Bootstrapping from a flat pile
The hierarchy is usually reached from below: an agent that started with one memory file and now keeps everything in it. The migration order matters, because each step is only cheap once the previous one is done.
First, split the recall pool. Creating one memory bank per domain is a configuration change, not a content rewrite — and it is the step with the highest leverage, because recall bleed stops the day the banks split. Content can migrate afterwards; the boundary should not wait for it.
Second, budget Layer 1. Set a character cap on the resident files, then audit what is already in them against the cap. Domain-specific facts become pointers to where they will live; what remains is what genuinely applies to every session.
Third, give the demoted facts a destination. One wiki directory per domain, with the one-writer and change-log discipline, receives what Layer 1 releases. Skills pick up the pointers to it last, because a skill that names a directory that does not exist yet is worse than no skill.
Where the hierarchy rots
The architecture is only as good as its maintenance, and each layer rots in a characteristic way.
Layer 1 fills first. It is the layer with the most convenient write path (“just remember this”), so it is the first to accumulate domain facts in disguise. The budget makes this visible: when the store is 90% full, audit it for entries that should be pointers. The fix is always the same move — demote facts to Layer 3, promote the signpost.
Layer 2 creeps second. Skills are where procedures and data want to live together, because “the procedure references the data constantly” feels reasonable at write time. The check is mechanical: if a skill body contains a table that is the source of truth for anything, it belongs in the wiki, and the skill should carry a path.
Layer 4 drifts silently. Retrieved memory is append-oriented and self-explanatory, so stale episodes are never corrected, only outlived. The recall preamble (“these memories are historical context, not verified facts”) is the standard mitigation. The cleaner mitigation is the same one Layer 3 uses: when an episode becomes a durable fact (“the client signed on this date at these terms”), it gets written into the system of record, where it is visible and editable, and the bank keeps only the narrative. A sharper variant of this drift — the agent’s own inference written back as evidence — is worked through in Self-Reinforcing Memory Loops in AI Agents.
Profiles multiply. Five profiles is manageable; fifteen is a fleet. The discipline is that a new profile appears only when a new domain appears — not for a new project, a new tool, or a new mood. Project-level separation is what the reference layer’s directory structure is for; domain-level separation is what profiles are for. Confusing the two is how people end up with a profile zoo and no clear recall story.
The takeaway: one placement rule
Put every piece of knowledge at the shallowest layer whose trigger matches its need: always-needed facts in resident memory as pointers, procedures in skills, reference data in files, episodes in a bank — and put each domain’s bank behind a profile that no other domain’s profile can recall. The agent then behaves like a well-designed system: the right knowledge is present because the right activity requested it, the wrong knowledge is absent because nothing in the conversation had a path to it, and the only thing that could force the two together is a change in configuration — something you make deliberately, and can therefore see when it happens.
The flat pile was never a discipline failure. It was an architecture where every fact shares one trigger, and that trigger is “always.” Break the trigger apart, and the leaks stop being a question of the model’s judgment. They stop being possible.
References
- PKM vs RAG vs Wiki vs Memory Systems — the foundational comparison of personal knowledge stores, retrieval pipelines, and agent memory
- Memory Systems in AI Assistants — the runtime memory stack this hierarchy sits inside
- Retrieval vs Representation in Knowledge Systems — why the shape of your store determines what it can answer
- AI Systems Memory hub
